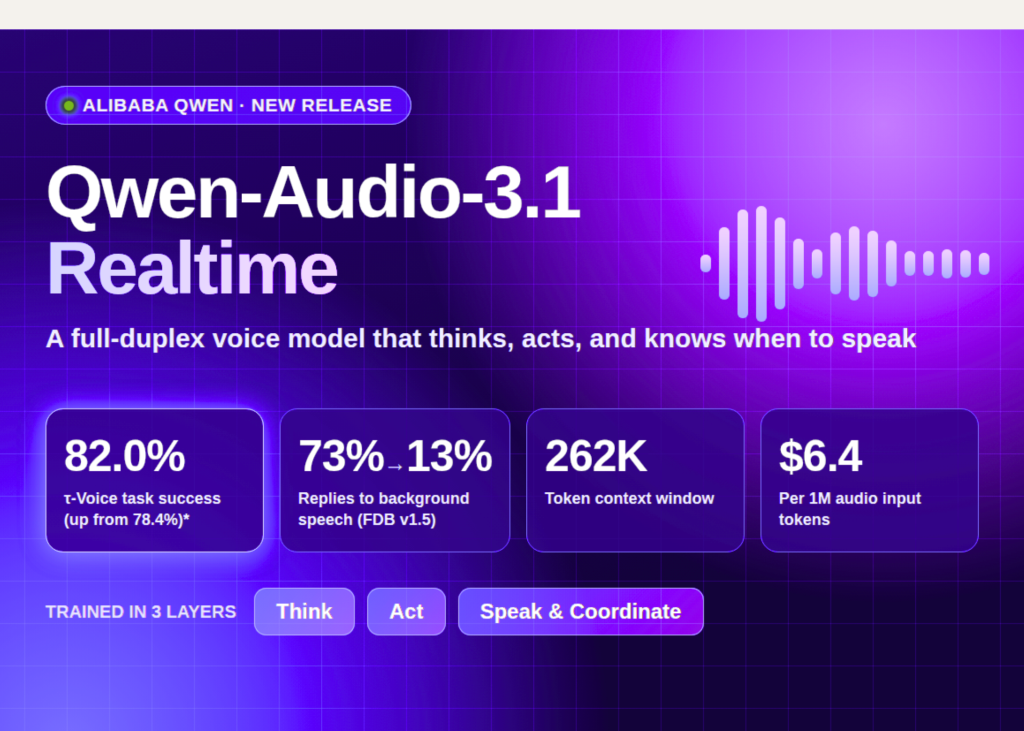
Alibaba’s Qwen team has released Qwen-Audio-3.1, a 5-model audio stack spanning ASR, TTS and realtime interaction. The main model is Qwen-Audio-3.1-Realtime, a full-duplex speech model built for voice agents that call tools. Qwen also cut prices: about 85% on Realtime, about 70% on TTS and up to 95% on ASR.
Is it deployable? Yes, as a managed API. qwen-audio-3.1-realtime-plus is live on QwenCloud over WebSocket. No open weights were announced.
What Ships on QwenCloud
The model page lists text and audio as both input and output. Context is 262K tokens, with 245K max input and 16K max output. Default limits are 60 requests and 100K tokens per minute. Pricing is $6.4 per 1M audio input tokens and $0.8 per 1M text input tokens. Text and audio output costs $24 per 1M tokens, with output text not charged. Key features include function calling, web search, structured outputs, context cache and fine-tuning.
A companion model, Qwen-Audio-3.1-ASR-Flash-Filetrans, targets offline long-audio transcription. It supports hot words, speaker separation, punctuation and multilingual plus Chinese dialect recognition. It costs $0.15 input and $0.47 output per 1M tokens.
Architecture: 2 Models Behind 1 Voice
The system runs 2 models with the same Audio Encoder and LLM design. A full-duplex decision model predicts whether to keep listening, speak, stop or resume. A speech-to-text model writes the response content as text. A context-aware voice renderer then turns that text into streaming speech. It conditions on conversation history, voice cues and acoustic context.
Training is organized into 3 layers: Think, Act, and Speak and Coordinate.
Think: M²-OPD
Core-Cocktail SFT re-anchors the audio model to its source text LLM using million-hour-scale paired data. Multimodality OPD follows. A Text Teacher and a frozen Audio Reference score each token of the student’s own trajectory. This is on-policy distillation, not imitation of pre-written answers. Domain experts for empathy, pragmatic intent and acoustic scenes are then trained with GRPO. Multi-Teacher OPD merges them into 1 deployable model.
Act: Executable Environments
Each training domain bundles a tool pool, a stateful JSON database and a natural-language business policy. Domains are seeded from open-source tool and MCP server definitions. Every task defines 1 of 3 outcomes: a write, a justified refusal, or an unsupported request. Scoring checks terminal state, then permitted writes, then behavioral assertions. A fluent reply cannot rescue a failed state check.
GRPO receives rewards at dialogue, milestone and turn level. Search training penalizes redundant queries with rquery=qmin(1,nrefnpred)r_{\text{query}} = q \min \left( 1, \frac{n_{\text{ref}}}{n_{\text{pred}}} \right). Mean queries per search call fell from 4.37 to 1.05. Trigger F1 slipped from 60.87% to 58.61%.
Speak and Coordinate
This layer decides whether, when and how to speak. On Full-Duplex-Bench v1.5, replies to people talking to someone else fell from 0.13 to 0.03. On v3.0, the filler rate dropped from 0.7590 to 0.2960. There are trade-offs. After interruptions, the unwanted resume rate rose from 0.035 to 0.130. Interruption stop latency is 1.116 seconds, versus 0.383 for GPT-Realtime-2.
Interactive Explainer
Explore the Think, Act, Speak loop, duplex decisions, a scored training episode and the search reward.
Benchmarks at a Glance
Against 3.0, Audio MultiChallenge rises from 47.12 to 52.21. The 14-language BBA average climbs from 81.7% to 88.1%. FLEURS WER falls from 9.01 to 3.98. The τ-Voice figures use a half-duplex speech-to-text adaptation. They are not comparable to official full-duplex results. GPT-Realtime-2 still leads the 50-session human red-team study, 96.00% versus 92.00%.
How It Compares
Prices are list rates checked September 28, 2026. Token rates are not directly comparable, since each provider tokenizes audio differently.
Key Takeaways
- Task success on a τ-Voice adaptation rises from 78.4% to 82.0% over 3.0.
- Replies to background speech drop from 73.0% to 13.0% on Full-Duplex-Bench v1.5.
- 262K context, function calling and web search at $6.4 per 1M audio input tokens.
- Tool use is trained with GRPO inside self-evolving executable environments.
- Multi-turn attack success falls to 26.0% (Chinese) and 23.5% (English).
FAQ
- What is Qwen-Audio-3.1-Realtime? A full-duplex speech model from Alibaba’s Qwen team for voice agents that reason, call tools and manage turn-taking.
- Can I self-host it? No open weights were announced. Access is through the QwenCloud API as qwen-audio-3.1-realtime-plus.
- How much does it cost? $6.4 per 1M audio input tokens and $24 per 1M output tokens for text and audio.
Check out the Paper, Qwen-Audio-3.1-ASR, and Qwen-Audio-3.1-Realtime. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Asif Razzaq is the CEO of Marktechpost AI Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.